

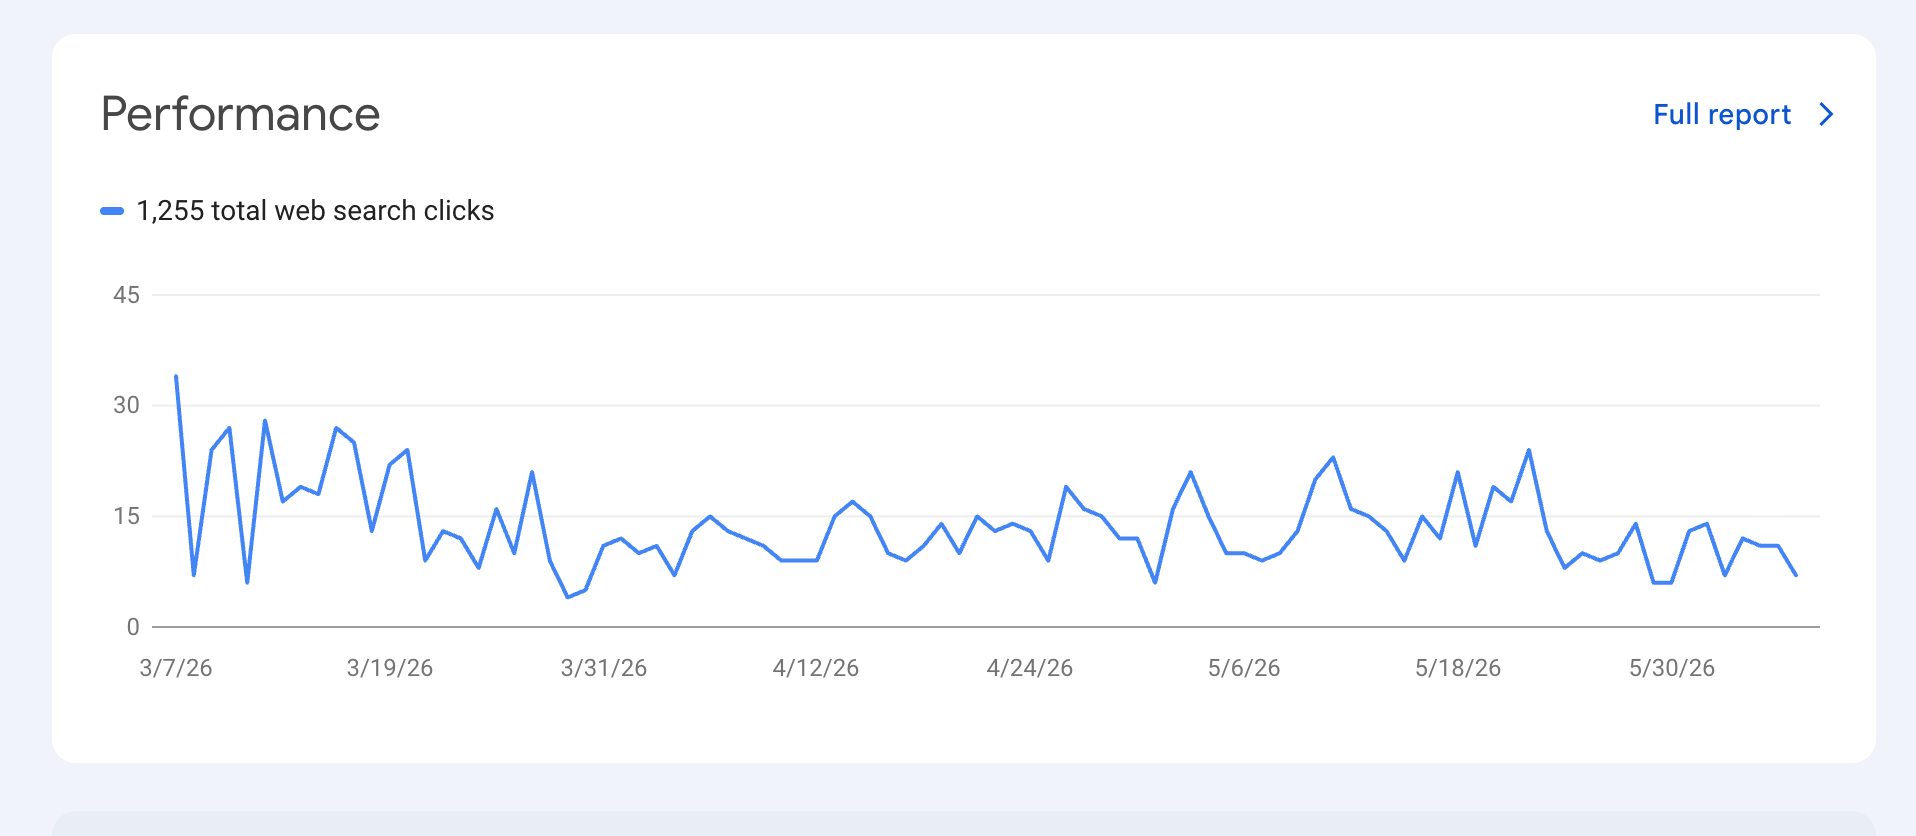
We have gotten several sites to ~1k visitors per month for free using this SEO workflow. We’ll walk through in detail how to build this system out yourself, what tools to use, and how to add AI to automate this.
We’ll also cover the tool we’re releasing soon to get this all done for you.
And stick the end for the exact visual breakdown of the automation, and the exact code we’re using to run this workflow.
Disclaimer — we can’t guarantee these results. We’ve been able to get our sites to this level of traffic due to many reasons, namely knowing the particular niche of the sites we built extremely well, giving us an edge into keywords that had yet to be explored.
The idea here is we build a topical cluster.
What this is essentially is a single pillar content piece with tons of details targeted to a specific keyword, then supporting keywords addressing adjacent topics.
For example, say we have a SaaS tool in the legal tech space that writes documents for attorneys. One topical cluster we write could have the following.
Pillar content — AI Legal Document Writing for Attorneys: The Complete Guide
And our supporting headlines…
[Workflow] How AI Fits Into a Law Firm’s Legal Drafting Process
[Governance] How Attorneys Review AI-Generated Legal Documents Safely
[Use Cases] Best Use Cases for AI in Legal Drafting
[Efficiency] How Law Firms Cut Drafting Time Without Losing Quality
[Competitor Tools] What to Look for in AI Legal Writing Software
[Hallucinations] How to Catch and Prevent AI Errors in Legal Documents
The idea here is any possible question a user can have regarding this particular topic we will have an answer to. Our pillar content will mention some of these, and each of our support headlines will handle the deep dive.
Let’s walk through each step of this process in detail, then wrap it up with a walk through of an AI workflow to put this all on auto pilot.
Finding the Pillar Keyword
What we want to do is find keywords that are a) high traffic and b) low competition.
Identifying Keywords — High Traffic
This step requires some creativity, and some domain expertise — the question we want to answer is, what questions are my customers/prospects/leads asking about this topic? And, can I deliver a meaningful answer to those questions?
A good keyword will bring in volume, and should ideally be something broad enough that a good number of your customers are searching for this term.
At the end of the day, keep in mind Google’s core value prop to their users — getting them the answers they were looking for. This should be our ultimate end goal as well, regardless of whether we use AI, hire copy writers to build these articles out, or write the articles ourselves.
Our favorite way of doing this beyond just knowing the niche extremely well is research.
Go to reddit, look at a few key subreddits for your particular niche, and sort by top results in the past week. An example from r/lawyertalk:
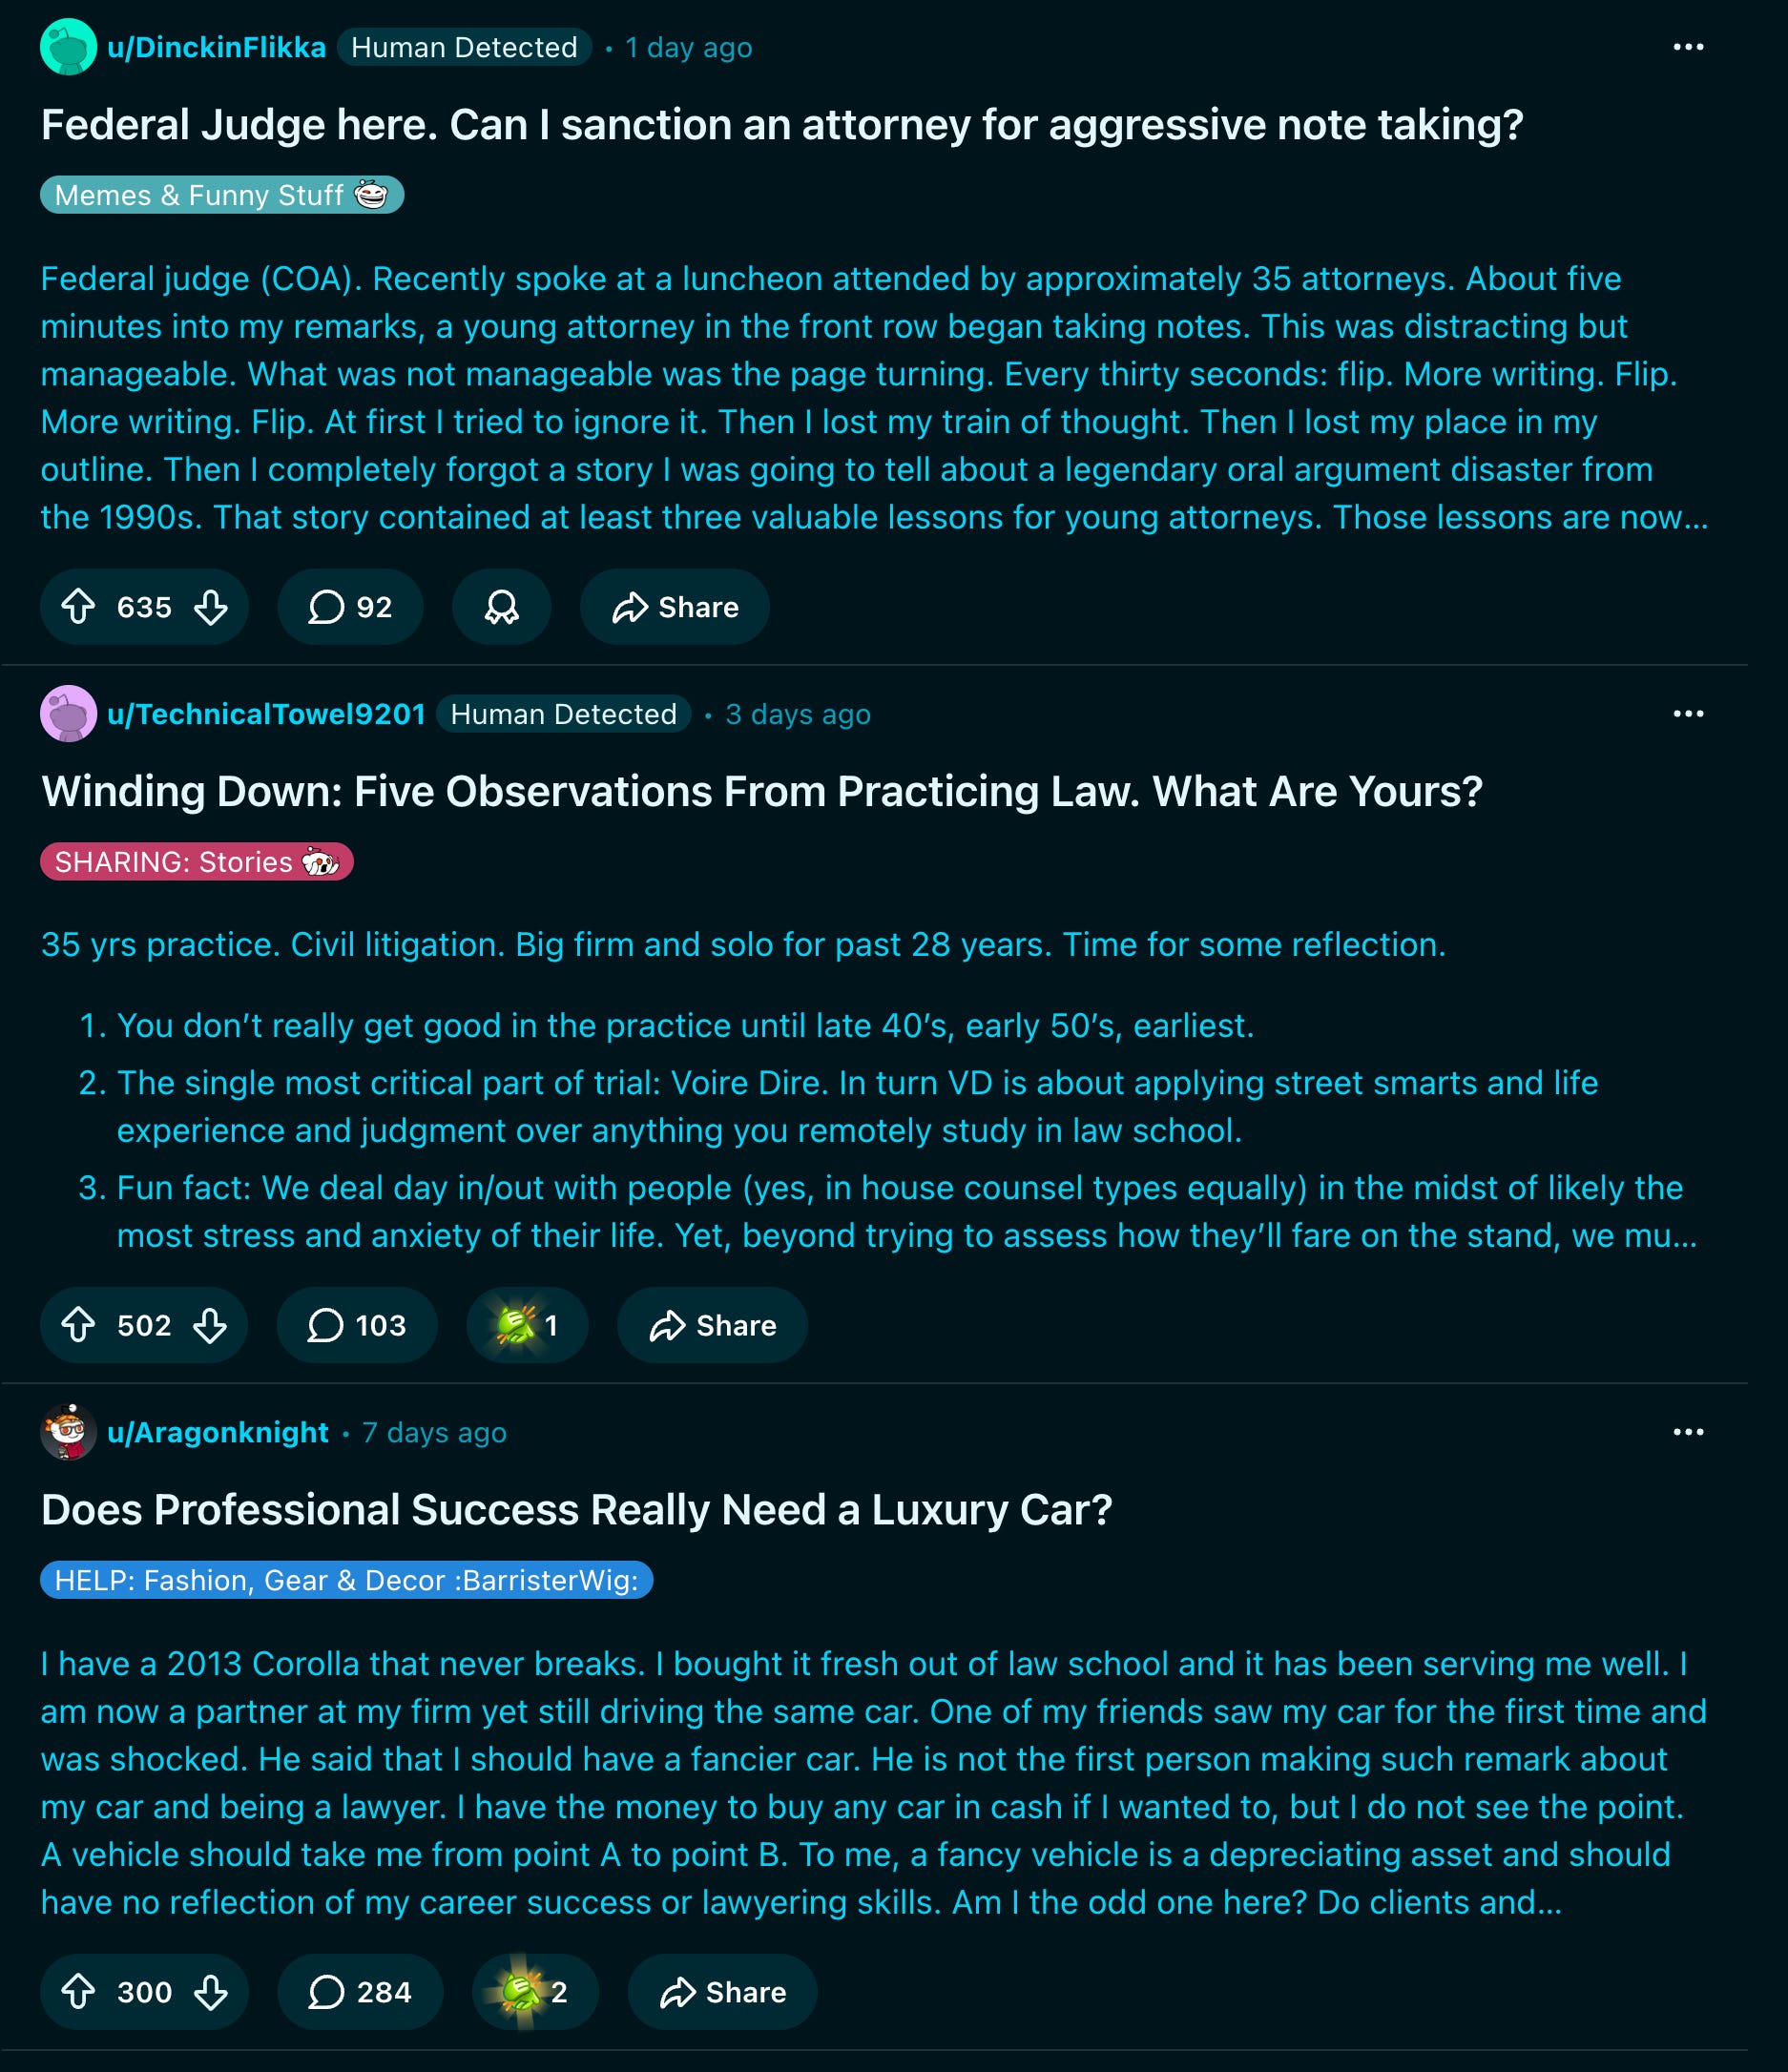
Questions from our ideal customers all sorted by upvotes — a quality list of prime questions to focus our keywords on.
The other thing to do is look at publications and look at the headlines of topics they’re addressing. Look at recent conferences and see what keynote topics were presented. This is another angle where knowing your domain well massively helps as you’ll know where your ideal customers are congregating.
Low Competition
After the above steps you should have some idea of keywords to go after.
To understand expected traffic volume, we have to now bring in some tooling.
We are developers, so we prefer to use DataForSEO. For a fraction of the cost they provide essentially all the data you’d get from a Ubersuggest, Semrush, or Ahrefs, without the expensive price tag.
But, use whatever SEO tool you prefer.
The idea here is we plugin our keyword and we start to get keyword difficulty scores and traffic volume estimates. We’re ideally looking for that sweet spot between difficulty and volume.
Identifying Supporting Headlines
Now at this point, we should’ve identified the core pillar keyword we’ll be writing.
We now need to build out our supporting headlines.
These will come from adjacent questions customers might have related to our core pillar topic, like we saw above. AI is great here — throw these now into a ChatGPT/Claude/Gemini and have the AI interrogate the pillar keyword for adjacent topics.
We want to cover as much ground with supporting headlines as possible to let Google know we have this topic well covered and that we are a definitive authority here.
Run the AI generated keywords again through your SEO tool, and again find that balance between difficulty and volume.
Writing
We’ve got all our headlines, now it’s time to give the customers they’re looking for.
Our pillar content ideally should be a long form article. 2k words minimum. After reading this piece, your customer should walk away a near expert in that particular topic.
The supporting articles we’ll write should ideally be around ~1k words each. The intended outcome from here is in case the customer wanted to explore anything in slightly more depth, the supporting headline articles can cover that without muddying the length of our pillar content too much.
As a last tip, improve your overall writing skills by reading fiction.
AI can generate thousands of words in an instant, but your particular point of view, applied to your particular niche, should result in an article that could not have existed without you.
Again, we want to be on the same side of the table as Google helping them provide value to their users. If our articles could just as easily be printed out by their own AI model Gemini, why should they bother giving you the search result?
Publishing
You’ll probably use whatever CMS your site is set up with to publish these posts whether that’s Wordpress, Webflow, or something more custom like a Sanity.io.
Important caveat here — we absolutely need to internally link our articles. Pillar content articles must link out to supporting articles, and supporting articles must link back to our pillar content.
This internal linking helps the Google crawler understand these articles are all related, and helps build Google’s confidence that our site is an expert in this topic.
Create some images for your articles, and release.
Results may vary, but we’ve seen websites we’ve built with well instrumented technical SEO (so proper sitemaps, well defined internal linking, and URL paths) start to get traffic within the first 30 days.
The AI Workflow
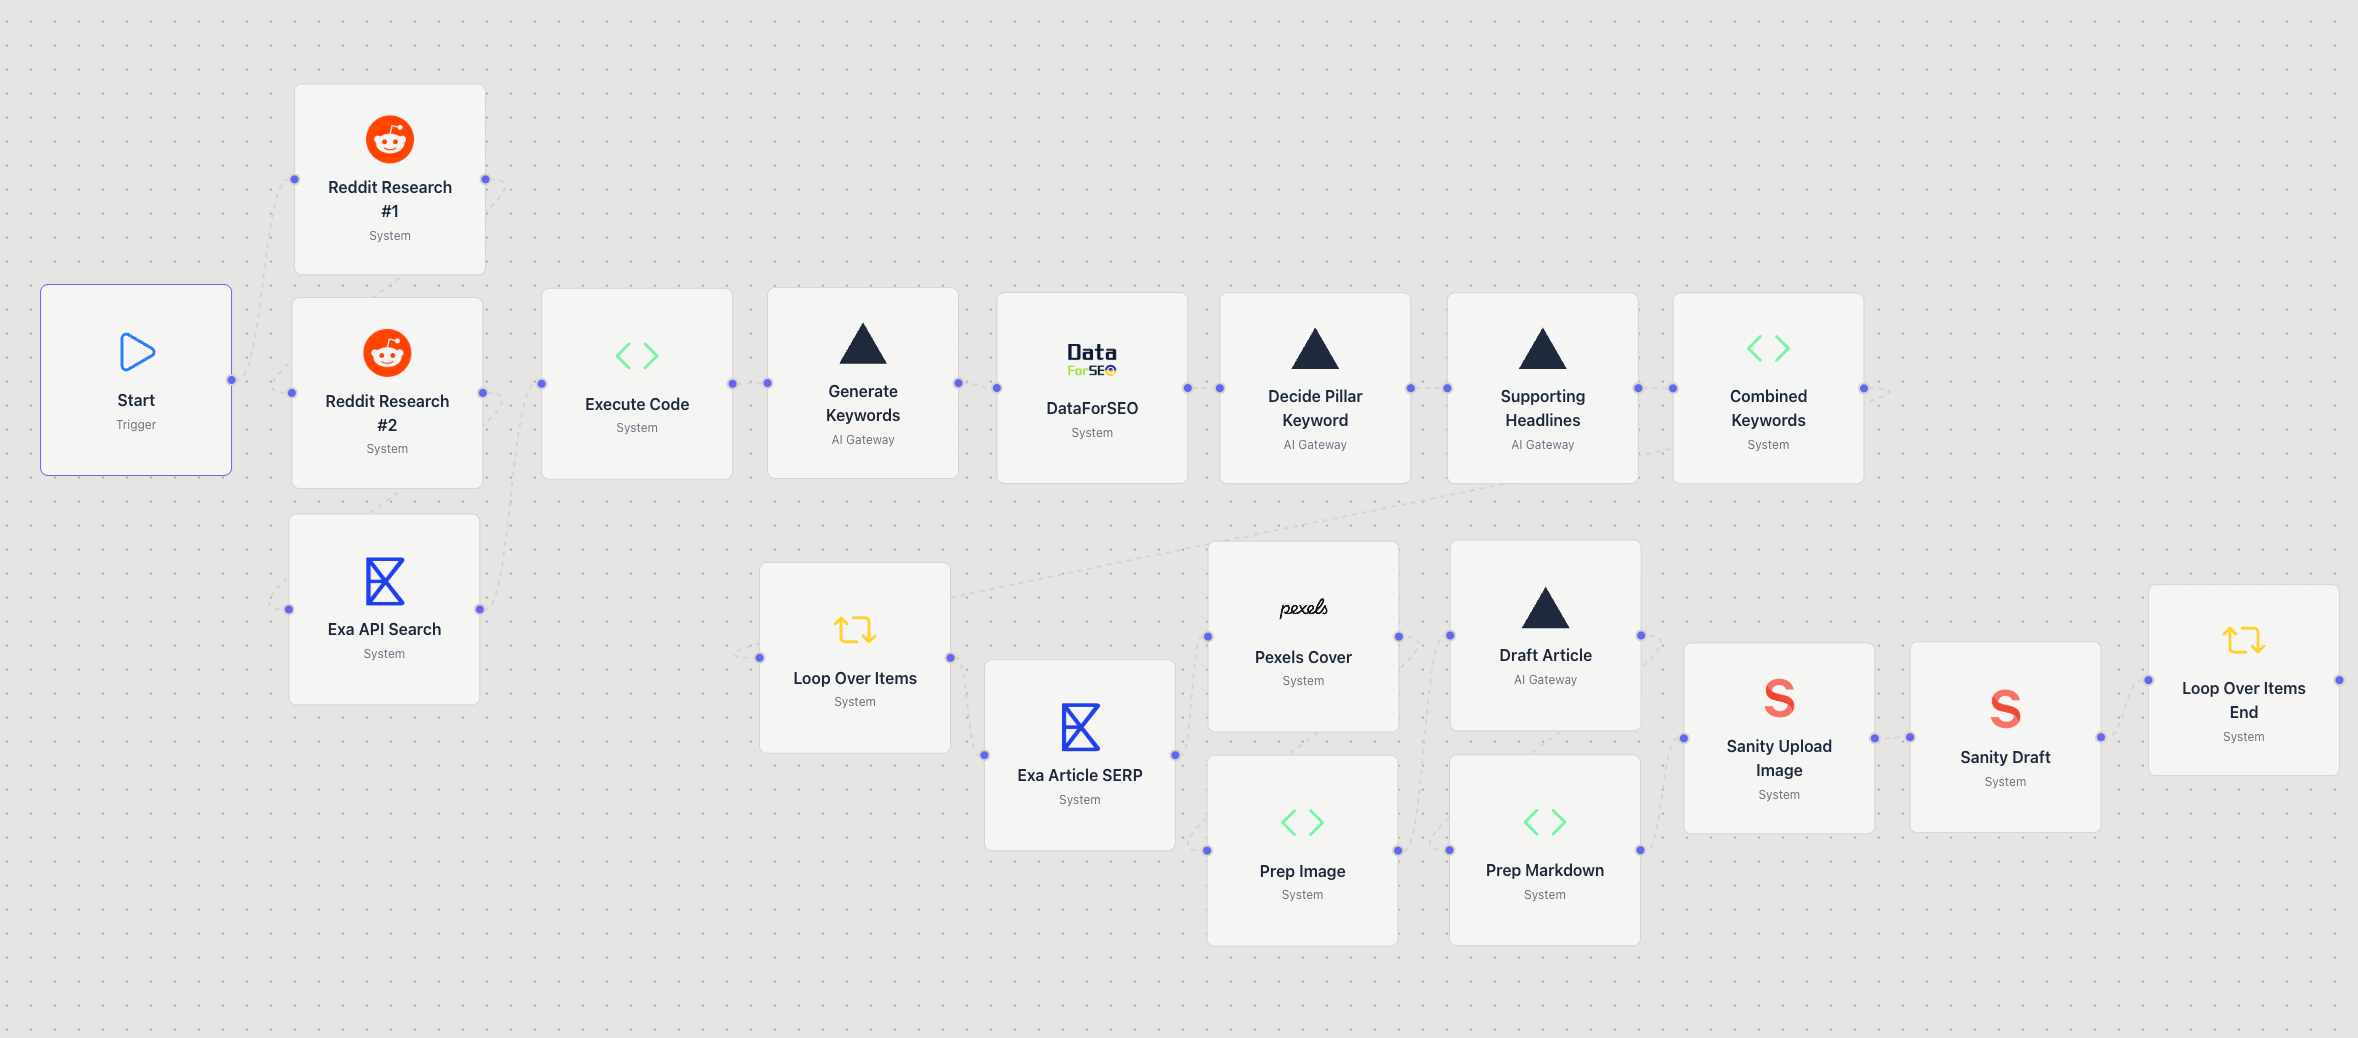
Of course being GTM Engineers, there’s no world where we’re doing this all manually. No, instead we’ve built out a custom AI workflow to handle this for us.
Here is the full breakdown of what’s happening in each step.
Reddit | Fetch weekly top posts from subreddit one
Reddit | Fetch weekly top posts from subreddit two
Exa | Search the web for related topic results
Code | Combine Reddit and Exa results into one research block
Claude | Generate pillar content keywords from the research
DataForSEO | Expand keywords with search volume and difficulty data
Claude | Pick one primary pillar keyword
Claude | Generate supporting article headlines
Code | Merge the pillar keyword and supporting headlines
Loop | Process each keyword one by one
Exa | Search SERP-style article results for the current keyword
Pexels | Find a cover image for the current keyword
Code | Download and base64-encode the cover image
Claude | Draft a full SEO article for the current keyword
Code | Convert the markdown article into portable text blocks
Sanity | Upload the cover image asset
Sanity | Create or replace the draft post document
The services you’ll need access to for this workflow are as follows.
Vercel AI Gateway
Exa API
Pexels
DataForSEO
Sanity CMS
Recreate this in your no-code editor of choice (Clay, n8n, Tray), or…
Next Stop: Draft Town
This entire workflow you’ve seen above is what we’re building as part of Draft Town. Sign up for our waitlist to be notified when we’re ready!
Vercel Workflow Code
And if you’re comfortable with code, below is a Vercel Workflow you can use today to spin this up yourself. Make any adjustments to the code with AI if needed — the code has all the context an agent would need.
export async function httpRequestStep(input: {
  endpoint: string;
  httpMethod: string;
  httpHeaders?: string;
  httpBody?: string;
}) {
  "use step";

  let headers = {};
  if (input.httpHeaders) {
    try {
      headers = JSON.parse(input.httpHeaders);
    } catch {
      // If parsing fails, use empty headers
    }
  }

  let body: string | undefined;
  if (input.httpMethod !== "GET" && input.httpBody) {
    try {
      const parsedBody = JSON.parse(input.httpBody);
      if (Object.keys(parsedBody).length > 0) {
        body = JSON.stringify(parsedBody);
      }
    } catch {
      if (input.httpBody.trim() && input.httpBody.trim() !== "{}") {
        body = input.httpBody;
      }
    }
  }

  const response = await fetch(input.endpoint, {
    method: input.httpMethod,
    headers,
    body,
  });

  const contentType = response.headers.get("content-type");
  if (contentType?.includes("application/json")) {
    return await response.json();
  }
  return await response.text();
}

export async function executeCodeStep(input: {
  code: string;
  language?: "javascript" | "typescript";
  outputs?: Record<string, { label: string; data: unknown }>;
}) {
  "use step";

  type NodeOutputs = Record<string, { label: string; data: unknown }>;

  function isStandardizedOutput(data: unknown): data is { success: boolean; data: unknown } {
    return (
      data !== null &&
      typeof data === "object" &&
      "success" in data &&
      "data" in data &&
      typeof (data as Record<string, unknown>).success === "boolean"
    );
  }

  function unwrapStandardizedOutput(data: unknown): unknown {
    return isStandardizedOutput(data) ? data.data : data;
  }

  function findNodeOutputByLabel(
    label: string,
    nodeOutputs: NodeOutputs
  ): { label: string; data: unknown } | undefined {
    const normalizedLabel = label.toLowerCase().trim();

    for (const output of Object.values(nodeOutputs)) {
      if (output.label.toLowerCase().trim() === normalizedLabel) {
        return output;
      }
    }

    return;
  }

  function resolveFieldPath(data: unknown, fieldPath: string): unknown {
    if (data === null || data === undefined) {
      return;
    }

    const parts = fieldPath.split(".");
    let current: unknown = data;

    const firstPart = parts[0]?.trim();
    if (
      isStandardizedOutput(current) &&
      firstPart !== "success" &&
      firstPart !== "data" &&
      firstPart !== "error"
    ) {
      current = current.data;
    }

    for (const part of parts) {
      const trimmedPart = part.trim();
      if (!trimmedPart) {
        continue;
      }

      const arrayMatch = trimmedPart.match(/^([^[]+)[(d+)]$/);
      if (arrayMatch) {
        const [, field, index] = arrayMatch;
        const fieldValue = (current as Record<string, unknown>)?.[field];
        if (Array.isArray(fieldValue)) {
          current = fieldValue[Number.parseInt(index, 10)];
        } else {
          current = undefined;
        }
      } else if (Array.isArray(current)) {
        current = current.map((item) => (item as Record<string, unknown>)?.[trimmedPart]);
      } else {
        current = (current as Record<string, unknown>)?.[trimmedPart];
      }

      if (current === undefined || current === null) {
        return;
      }
    }

    return current;
  }

  function resolveTemplateReference(expression: string, outputs: NodeOutputs): unknown {
    const trimmed = expression.trim();

    if (trimmed.startsWith("@")) {
      const withoutAt = trimmed.substring(1);
      const colonIndex = withoutAt.indexOf(":");
      if (colonIndex === -1) {
        return;
      }

      const nodeId = withoutAt.substring(0, colonIndex);
      const rest = withoutAt.substring(colonIndex + 1);
      const dotIndex = rest.indexOf(".");
      const nodeOutput = outputs[nodeId];

      if (!nodeOutput) {
        return;
      }

      if (dotIndex === -1) {
        return unwrapStandardizedOutput(nodeOutput.data);
      }

      return resolveFieldPath(nodeOutput.data, rest.substring(dotIndex + 1));
    }

    if (trimmed.startsWith("$")) {
      const withoutDollar = trimmed.substring(1);
      const parts = withoutDollar.split(".");
      const nodeId = parts[0];
      const nodeOutput = outputs[nodeId];

      if (!nodeOutput) {
        return;
      }

      if (parts.length === 1) {
        return unwrapStandardizedOutput(nodeOutput.data);
      }

      return resolveFieldPath(nodeOutput.data, parts.slice(1).join("."));
    }

    const dotIndex = trimmed.indexOf(".");
    if (dotIndex === -1) {
      const nodeOutput = findNodeOutputByLabel(trimmed, outputs);
      return nodeOutput ? unwrapStandardizedOutput(nodeOutput.data) : undefined;
    }

    const label = trimmed.substring(0, dotIndex);
    const fieldPath = trimmed.substring(dotIndex + 1);
    const nodeOutput = findNodeOutputByLabel(label, outputs);
    if (!nodeOutput) {
      return;
    }

    return resolveFieldPath(nodeOutput.data, fieldPath);
  }

  function serializeTemplateValue(value: unknown): string {
    if (value === undefined) {
      return "undefined";
    }
    if (value === null) {
      return "null";
    }
    if (typeof value === "string") {
      return JSON.stringify(value);
    }
    if (
      typeof value === "number" ||
      typeof value === "boolean" ||
      typeof value === "bigint"
    ) {
      return String(value);
    }

    try {
      const json = JSON.stringify(value);
      return json ?? "undefined";
    } catch {
      return "undefined";
    }
  }

  function replaceTemplateReferences(code: string, outputs: NodeOutputs): string {
    return code.replace(/{{([^}]+)}}/g, (match, expression) => {
      const resolved = resolveTemplateReference(expression, outputs);
      if (resolved === undefined) {
        return "undefined";
      }

      return serializeTemplateValue(resolved);
    });
  }

  async function transpileCode(code: string, language?: "javascript" | "typescript") {
    if (language === "javascript") {
      return code;
    }

    const ts = await import("typescript");
    const result = ts.transpileModule(code, {
      compilerOptions: {
        target: ts.ScriptTarget.ES2022,
        module: ts.ModuleKind.ESNext,
      },
      fileName: "execute-code.ts",
    });

    return result.outputText;
  }

  function isStandardResult(value: unknown): value is { success: boolean; data?: unknown; error?: { message: string } } {
    return (
      typeof value === "object" &&
      value !== null &&
      "success" in value &&
      typeof (value as { success?: unknown }).success === "boolean"
    );
  }

  const outputs = input.outputs || {};
  const transformedCode = replaceTemplateReferences(input.code, outputs);
  const compiledCode = await transpileCode(transformedCode, input.language);
  const AsyncFunction = Object.getPrototypeOf(async function () {}).constructor;

  try {
    const fn = new AsyncFunction(
      "input",
      "outputs",
      ""use strict";
" + compiledCode
    ) as (input: unknown, outputs: NodeOutputs) => Promise<unknown>;

    const result = await fn(input, outputs);
    if (isStandardResult(result)) {
      return result;
    }

    return { success: true, data: result };
  } catch (error) {
    const message = error instanceof Error ? error.message : String(error);
    return { success: false, error: { message: "Code execution failed: " + message } };
  }
}

export async function executeWorkflow() {
  "use workflow";

  // Reddit Research #1
  const redditResearch1Result = await httpRequestStep({
    endpoint: `https://www.reddit.com/r/{SUBREDDIT_ONE}/top.json?t=week&limit=15`,
    httpMethod: `GET`,
    httpHeaders: `{"User-Agent": "workflow/1.0" }`,
    responseSchema: `[{"id":"Xpk_M_jWc-6rvA-7BIox9","name":"data","type":"object","fields":[{"id":"ui-EU7NR4fKpdJESLR1Nz","name":"children","type":"array","itemType":"object","fields":[{"id":"rTPkyBpVJYHSfEnEdU55F","name":"data","type":"object","fields":[{"id":"Hthxh2O5RRz1A66TT_SPN","name":"title","type":"string"},{"id":"xJMq8XGl3iSV3q7ZoEPbg","name":"num_comments","type":"number"},{"id":"gpXIBcFh_jZOkNj9wEGCD","name":"url","type":"string"},{"id":"jxSI4KEU_-LBX4Yj0FAdu","name":"subreddit","type":"string"}]}]}]}]`,
  });

  // Reddit Research #2
  const redditResearch2Result = await httpRequestStep({
    endpoint: `https://www.reddit.com/r/{SUBREDDIT_TWO}/top.json?t=week&limit=15`,
    httpMethod: `GET`,
    httpHeaders: `{"User-Agent": "workflow/1.0" }`,
    responseSchema: `[{"id":"Xpk_M_jWc-6rvA-7BIox9","name":"data","type":"object","fields":[{"id":"ui-EU7NR4fKpdJESLR1Nz","name":"children","type":"array","itemType":"object","fields":[{"id":"rTPkyBpVJYHSfEnEdU55F","name":"data","type":"object","fields":[{"id":"Hthxh2O5RRz1A66TT_SPN","name":"title","type":"string"},{"id":"xJMq8XGl3iSV3q7ZoEPbg","name":"num_comments","type":"number"},{"id":"gpXIBcFh_jZOkNj9wEGCD","name":"url","type":"string"},{"id":"jxSI4KEU_-LBX4Yj0FAdu","name":"subreddit","type":"string"}]}]}]}]`,
  });

  // Exa API Search
  const exaApiSearchResult = await httpRequestStep({
    endpoint: `https://api.exa.ai/search`,
    httpBody: `{}`,
    httpHeaders: `{
"accept": "application/json",
"content-type": "application/json",
"x-api-key": "${process.env.EXA_API_KEY ?? ""}"
}`,
    responseSchema: `[{"id":"Stf2fdkAaWpn8myJYzENh","name":"results","type":"array","itemType":"object","fields":[{"id":"0kvMPEk4IyJkpaZYrcFiN","name":"title","type":"string"},{"id":"fTPxn3v72khgG9OEwSt5K","name":"url","type":"string"},{"id":"AHDFt7mnIqi7rpXLZuulD","name":"text","type":"string"}]}]`,
  });

  // Execute Code
  const executeCodeResult = await executeCodeStep({
    code: `let joinedResults = '';

joinedResults += "Reddit research #1";
joinedResults += ${redditResearch1Result.data.data.children}.join("\n\n");

joinedResults += "Reddit research #2";
joinedResults += ${redditResearch2Result.data.data.children}.join("\n\n");

joinedResults += "Exa API Web Search";
joinedResults += ${exaApiSearchResult.data.results}.join("\n\n");

return { success: true, data: joinedResults };`,
    codeLanguage: `typescript`,
    outputSchema: `[{"id":"nu7ZN3OtUYLR3wnpQs2sI","name":"success","type":"boolean"},{"id":"TR3yX_kc7at8VqLxWUL05","name":"data","type":"string","description":"Large text block containing all subreddit and exa web search results"}]`,
  });

  // Generate Keywords
  const generateKeywordsResult = await generateTextStep({
      aiFormat: "object",
      aiModel: "anthropic/claude-opus-4.8",
      aiPrompt: `Generate a set of pillar content keywords here for an SEO topical cluster we are writing.

The following are results from the most recent week of posts on subreddits, and some web search results for this topic.

${executeCodeResult.data}`,
      aiSchema: "[{\"id\":\"D8OJLcLL1CuGAVXU7bGOW\",\"name\":\"keywords\",\"type\":\"array\",\"itemType\":\"string\"}]",
  });

  // DataForSEO
  const dataforseoResult = await httpRequestStep({
    endpoint: `https://api.dataforseo.com/v3/dataforseo_labs/google/keyword_ideas/live`,
    httpBody: `[
    {
      "keywords": ${generateKeywordsResult.object.keywords},
      "location_code": 2840,
      "language_code": "en",
      "include_serp_info": true,
      "limit": 100
    }
  ]`,
    httpHeaders: `{
    "Authorization": "Basic BASE64(${process.env.DATA_FOR_SEO_LOGIN ?? ""})",
    "Content-Type": "application/json"
}`,
    responseSchema: `[{"id":"DdQkPXzTG5Ne-KG6u-QF8","name":"tasks","type":"array","itemType":"object","fields":[{"id":"2XLQ3jAekE7ptodJ0v-Ln","name":"result","type":"array","itemType":"object","fields":[{"id":"u73bleICbIBwM7RT8YZmB","name":"items","type":"array","itemType":"object","fields":[{"id":"MnQJ0aPSAEH-qNJVJfjFB","name":"keyword","type":"string"},{"id":"uWuoQreAiWJrIHOuMb4Sl","name":"keyword_info","type":"object","fields":[{"id":"ZqYe5QFaRSvdSuHBjpONh","name":"search_volume","type":"number"},{"id":"LC5SLLbA_xkRSpVlCt7QJ","name":"keyword_difficulty","type":"number"}]}]}]}]}]`,
  });

  // Decide Pillar Keyword
  const decidePillarKeywordResult = await generateTextStep({
      aiModel: "anthropic/claude-sonnet-4.0",
      aiPrompt: `Between these keywords, find the maximum traffic volume for a mid-range, approachable keyword difficulty. Return with just one keyword.

${dataforseoResult.data.tasks}
`,
  });

  // Supporting Headlines
  const supportingHeadlinesResult = await generateTextStep({
      aiFormat: "object",
      aiModel: "anthropic/claude-opus-4.8",
      aiPrompt: `Generate multiple supporting article headlines adjacent to this topic so we can have as much coverage on potential questions readers might have surrounding this topic.

Max of 10.`,
      aiSchema: "[{\"id\":\"RwHSUdfWgvKSBz3_7Hf5B\",\"name\":\"headlines\",\"type\":\"array\",\"itemType\":\"string\"}]",
  });

  // Combined Keywords
  const combinedKeywordsResult = await executeCodeStep({
    code: `// This block runs as the body of an async function.
// Use {{NodeName.property}} to interpolate workflow data before execution.
const joinedKeywords = [
  ${decidePillarKeywordResult.text},
  ...${supportingHeadlinesResult.object.headlines},
];

return { success: true, data: joinedKeywords };`,
    codeLanguage: `typescript`,
    outputSchema: `[{"id":"wo1h2fQPberc4tliA1m30","name":"success","type":"boolean"},{"id":"ms9uAE25Bb1Q_4Gzhe8Mk","name":"data","type":"array","itemType":"string"}]`,
  });

  // Loop Over Items
  const loopItems = ${combinedKeywordsResult.data};
  for (const [loopIndex, loopItem] of loopItems.entries()) {
    outputs['_WEViX4oGR0R1f2s9Amdp'] = { label: "Loop Over Items", data: { items: loopItems, item: loopItem, index: loopIndex, total: loopItems.length } };
    // Exa Article SERP
    const exaArticleSerpResult = await httpRequestStep({
      endpoint: `https://api.exa.ai/search`,
      httpBody: `{
  "query": "${loopOverItemsResult.item}",
  "type": "auto",
  "contents": {
    "text": true
  }
}

`,
      httpHeaders: `{
"accept": "application/json",
"content-type": "application/json",
"x-api-key": "${process.env.EXA_API_KEY ?? ""}"
}`,
      responseSchema: `[{"id":"Stf2fdkAaWpn8myJYzENh","name":"results","type":"array","itemType":"object","fields":[{"id":"0kvMPEk4IyJkpaZYrcFiN","name":"title","type":"string"},{"id":"fTPxn3v72khgG9OEwSt5K","name":"url","type":"string"},{"id":"AHDFt7mnIqi7rpXLZuulD","name":"text","type":"string"}]}]`,
    });

    // Pexels Cover
    const pexelsCoverResult = await httpRequestStep({
      endpoint: `https://api.pexels.com/v1/search?query=${loopOverItemsResult.item}&per_page=1&orientation=landscape`,
      httpMethod: `GET`,
      httpHeaders: `{
  "Authorization": "${process.env.PEXELS_API_KEY ?? ""}"
}`,
      responseSchema: `[{"id":"EqCcfRYYUQj5YkxBY8vI6","name":"url","type":"string"}]`,
    });

    // Prep Image
    const prepImageResult = await executeCodeStep({
      codeLanguage: `typescript`,
      code: `const imgRes = await fetch(${pexelsCoverResult.data.url})
if (!imgRes.ok) throw new Error(\`Image fetch failed: ${imgRes.status}\`)

const contentType = imgRes.headers.get("content-type") || "image/png"
const buffer = Buffer.from(await imgRes.arrayBuffer())

const data = {
  cover: {
    filename: \`cover-${slug}.png\`,
    contentType,
    base64: buffer.toString("base64"),
  }
}

return { success: true, data };`,
      outputSchema: `[{"id":"JH3KFs0H3o9SUjXgCGwcO","name":"data","type":"object","fields":[{"id":"KtrOfNfGdIWyBjDbAfmYg","name":"filename","type":"string"},{"id":"-70oT7BaRDkqQe89SNxCi","name":"contentType","type":"string"},{"id":"58Y9vuj2cH6mUtwJjqlNt","name":"base64","type":"string"}]}]`,
    });

    // Draft Article
    const draftArticleResult = await generateTextStep({
        aiModel: "anthropic/claude-opus-4.8",
        aiPrompt: `Write a full SEO article in GitHub-flavored markdown about: ${loopOverItemsResult.item}

Make it 1800-2200 words. Start with an H1 that matches the topic. Use short sentences and short paragraphs. Include H2s and H3s, at least one list, and at least one concrete example.

Keep it grounded in real problems, specific, and practical. No jargon, no hype, no marketing fluff. Explain the workflow, common failure points, and how to evaluate solutions. End with a natural conclusion and a single CTA line.

Return only the markdown body. Do not include YAML frontmatter.

Below is research covered by existing articles -- we should mention what we need to in order to cover the topic, but see if we can extend or add more color to the topic already covered by the existing SERP results.

${exaArticleSerpResult.data.results}`,
    });

    // Prep Markdown
    const prepMarkdownResult = await executeCodeStep({
      codeLanguage: `typescript`,
      code: `function key() {
  return Math.random().toString(36).slice(2, 12)
}

function cleanInline(text) {
  return String(text)
    .replace(/\[([^\]]+)\]\(([^)]+)\)/g, '$1')
    .replace(/\`([^\`]+)\`/g, '$1')
    .replace(/\*\*([^*]+)\*\*/g, '$1')
    .replace(/\*([^*]+)\*/g, '$1')
    .replace(/__([^_]+)__/g, '$1')
    .replace(/_([^_]+)_/g, '$1')
    .trim()
}

function makeBlock(text, style = 'normal', extra = {}) {
  return {
    _type: 'block',
    _key: key(),
    style,
    markDefs: [],
    children: [
      {
        _type: 'span',
        _key: key(),
        text: cleanInline(text),
        marks: [],
      },
    ],
    ...extra,
  }
}

function markdownToPortableText(markdown) {
  const lines = String(markdown || '')
    .replace(/\r\n/g, '\n')
    .split('\n')

  const blocks = []
  let paragraph = []

  function flushParagraph() {
    const text = paragraph.join(' ').trim()
    if (text) blocks.push(makeBlock(text))
    paragraph = []
  }

  for (let i = 0; i < lines.length; i++) {
    const line = lines[i].trim()

    if (!line) {
      flushParagraph()
      continue
    }

    if (/^#{1,3}\s+/.test(line)) {
      flushParagraph()
      const level = line.match(/^#{1,3}/)[0].length
      const text = line.replace(/^#{1,3}\s+/, '')
      blocks.push(makeBlock(text, \`h${level}\`))
      continue
    }

    if (/^[-*]\s+/.test(line)) {
      flushParagraph()
      const text = line.replace(/^[-*]\s+/, '')
      blocks.push(makeBlock(text, 'normal', { listItem: 'bullet', level: 1 }))
      continue
    }

    if (/^\d+\.\s+/.test(line)) {
      flushParagraph()
      const text = line.replace(/^\d+\.\s+/, '')
      blocks.push(makeBlock(text, 'normal', { listItem: 'number', level: 1 }))
      continue
    }

    if (/^\`\`\`/.test(line)) {
      flushParagraph()
      const codeLines = []
      i += 1
      while (i < lines.length && !/^\`\`\`/.test(lines[i].trim())) {
        codeLines.push(lines[i])
        i += 1
      }
      const codeText = codeLines.join('\n')
      if (codeText.trim()) blocks.push(makeBlock(codeText, 'normal'))
      continue
    }

    paragraph.push(line)
  }

  flushParagraph()
  return blocks
}

const body = markdownToPortableText(${draftArticleResult.text})

return {
  success: true,
  data: {
    body
  }
}`,
      outputSchema: `[{"id":"DzeT4jTSCblxWGH6L-eNb","name":"data","type":"object","fields":[{"id":"JW1rPsfpr9mmsyhWPSfbU","name":"body","type":"array","itemType":"object"}]}]`,
    });

    // Sanity Upload Image
    const sanityUploadImageResult = await httpRequestStep({
      endpoint: `https://${process.env.SANITY_PROJECT_ID ?? ""}.api.sanity.io/v2024-01-01/assets/images/${process.env.SANITY_DATASET ?? ""}?filename=cover-${loopOverItemsResult.item}.png`,
      httpHeaders: `{
    "Authorization": "Bearer ${process.env.SANITY_WRITE_KEY ?? ""}",
    "Content-Type": "image/png"
  }`,
      responseSchema: `[{"id":"I6DOl4K5tFnWYrPMsSs7f","name":"assetId","type":"string"}]`,
      httpBody: `{
  body: "${prepImageResult.data.base64}"
}
`,
    });

    // Sanity Draft
    const sanityDraftResult = await httpRequestStep({
      endpoint: `https://${process.env.SANITY_PROJECT_ID ?? ""}.api.sanity.io/v2024-01-01/data/mutate/${process.env.SANITY_DATASET ?? ""}`,
      httpHeaders: `{
    "Authorization": "Bearer ${process.env.SANITY_WRITE_KEY ?? ""}",
    "Content-Type": "image/png"
  }`,
      httpBody: `{
    "mutations": [
      {
        "createOrReplace": {
          "_id": "drafts.post-YOUR_SLUG",
          "_type": "post",
          "title": "Your title",
          "slug": {
            "_type": "slug",
            "current": "your-slug"
          },
          "isDoc": false,
          "publishedAt": "2026-06-12T00:00:00.000Z",
          "image": {
            "_type": "image",
            "asset": {
              "_type": "reference",
              "_ref": "${sanityUploadImageResult.data.assetId}"
            },
            "alt": "Your title"
          },
          "body":
${prepMarkdownResult.data.body}
     }
    }
  ]
}`,
    });

    // Loop Over Items End
  }
  outputs['_WEViX4oGR0R1f2s9Amdp'] = { label: "Loop Over Items", data: { items: loopItems, iterations: loopItems.length } };
}